
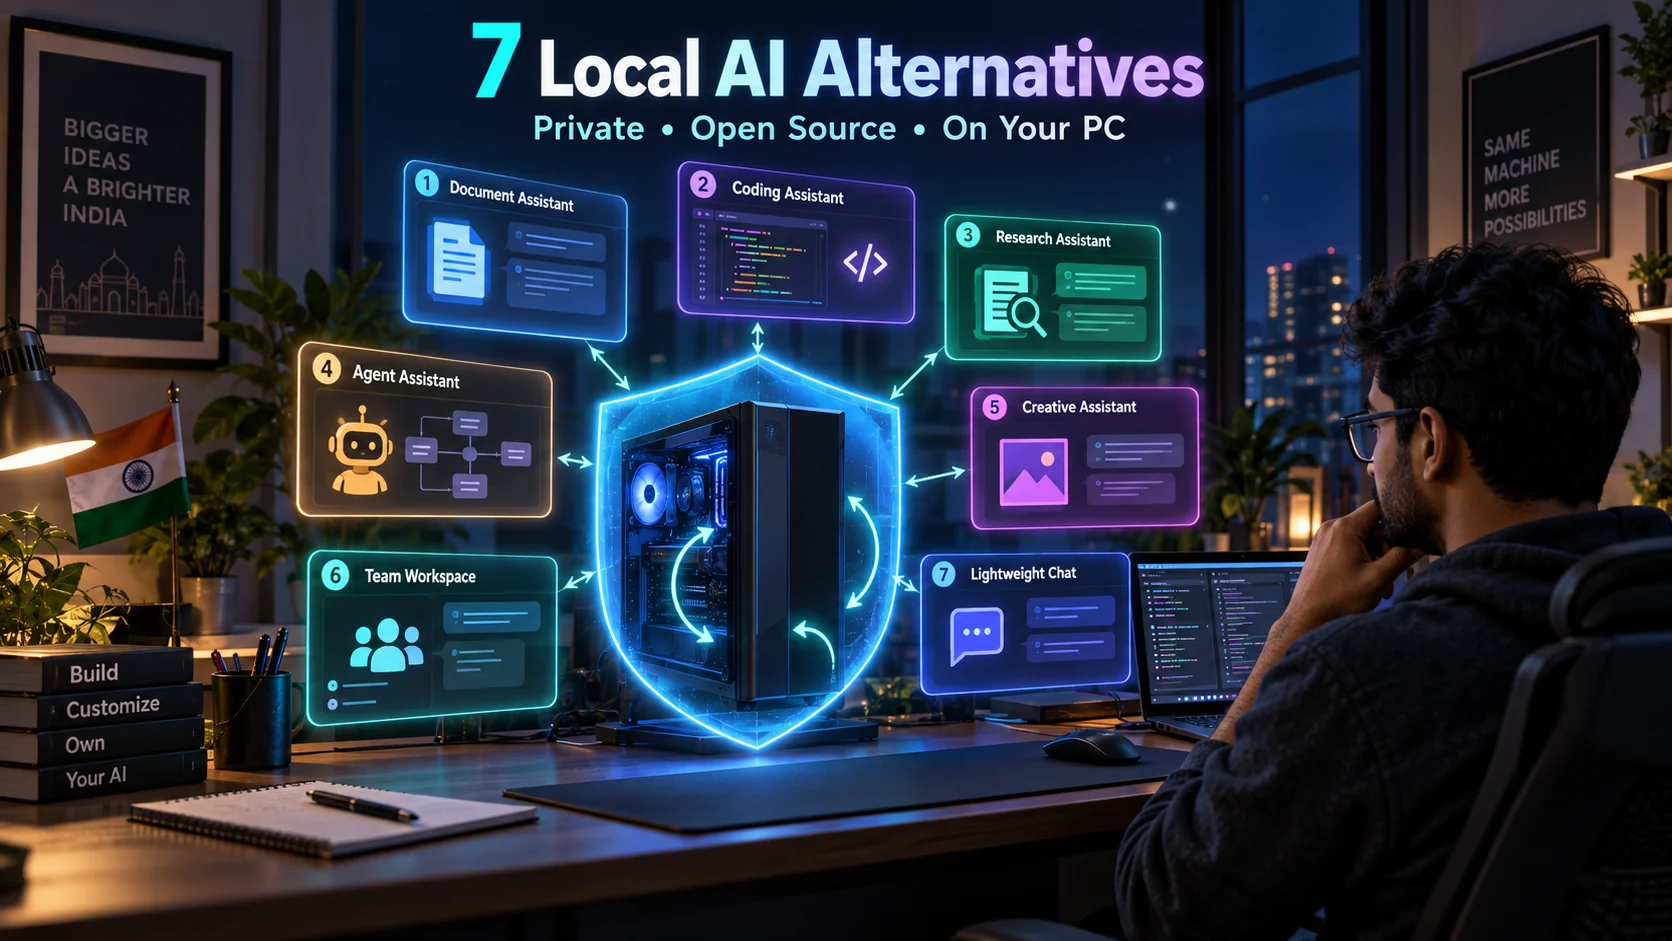
ChatGPT के 7 Open-Source Alternatives जिन्हें अपने Computer पर Local चला सकते हैं
Open WebUI, llama.cpp WebUI, LobeChat, AnythingLLM, Jan, LibreChat और Chat UI की detailed Hindi comparison guide—privacy, hardware, setup और सही use case सहित।
Cloud AI assistants सुविधाजनक हैं, लेकिन sensitive documents, recurring subscription cost, internet dependency और data control के कारण कई users local AI विकल्प देख रहे हैं। Local setup में language model आपके computer या अपने server पर चलता है और browser या desktop app के जरिए ChatGPT जैसी conversation मिल सकती है।
लेकिन “local AI” एक single application नहीं है। इसमें model, runtime और chat interface अलग components होते हैं। सही tool चुनने से पहले यह समझना जरूरी है कि कौन-सा software model चलाता है, कौन केवल interface देता है और कौन documents, agents या multi-user access जोड़ता है। यह guide सात practical alternatives को इसी नजरिए से compare करती है। AI-generated content की quality और human review से जुड़े risks समझने के लिए हमारी AI content review guide भी पढ़ें।
पहले तीन layers समझें: Model, Runtime और Interface
| Layer | काम | Examples | गलतफहमी |
|---|---|---|---|
| AI model | Text समझता और response बनाता है | Different instruction, coding or vision models | हर open model unrestricted नहीं होता |
| Runtime | Model को CPU/GPU पर load और run करता है | llama.cpp, Ollama-compatible server | UI install करने से model अपने आप नहीं चलता |
| Interface | Chat, history, files, users और tools देता है | Open WebUI, LibreChat, Chat UI | Local interface cloud API से जुड़ा हो तो prompts cloud पर जा सकते हैं |
Privacy का दावा तभी सही है जब पूरा request path local हो: interface, model endpoint, embeddings, speech, web search और document processing। केवल browser address में localhost दिखना पर्याप्त proof नहीं है।
Quick comparison: किसके लिए कौन-सा विकल्प?
| Tool | Best for | Setup level | Model backend | Multi-user |
|---|---|---|---|---|
| Open WebUI | Complete private AI workspace | Medium | Ollama and compatible APIs | Yes |
| llama.cpp WebUI | Lightweight direct GGUF use | Technical | Built into llama-server | Limited/advanced configuration |
| LobeChat | Polished chat and agents | Medium | Local or compatible APIs | Deployment-dependent |
| AnythingLLM | Documents and private knowledge bases | Easy to medium | Built-in or external providers | Server edition |
| Jan | Beginner-friendly desktop local AI | Easy | llama.cpp or MLX | Primarily personal desktop |
| LibreChat | Teams, agents and many providers | Advanced | Local and cloud endpoints | Yes |
| Chat UI | Developer-controlled clean frontend | Advanced | OpenAI-compatible endpoint | Authentication supported |
1. Open WebUI: complete local AI workspace
Open WebUI उन users के लिए strong option है जिन्हें browser-based polished chat, multiple models, files, knowledge collections, tools और user management एक जगह चाहिए। इसे Docker या supported Python setup से चलाया जा सकता है और local model server से connect किया जा सकता है।
| Strength | Why it matters |
|---|---|
| Provider-agnostic interface | Local और compatible remote endpoints दोनों manage कर सकता है |
| Knowledge/RAG | Documents को searchable knowledge base में organize कर सकते हैं |
| User management | Family, team या internal organisation setup में उपयोगी |
| Docker deployment | Updates, persistent volumes और server hosting manageable होती है |
| Extensibility | Tools, web search और other services जोड़ी जा सकती हैं |
किसके लिए: Home server, small team, private knowledge assistant और multiple local models। ध्यान दें: Web search, external embeddings या cloud provider enable करने पर relevant data machine से बाहर जा सकता है। हर connection अलग verify करें।
2. llama.cpp WebUI: सबसे direct और lightweight route
llama.cpp quantized GGUF models को consumer hardware पर चलाने के लिए widely used runtime है। llama-server के साथ web interface और compatible API मिलती है, इसलिए अलग heavy chat platform लगाए बिना model से browser में बात की जा सकती है।
| Advantage | Trade-off |
|---|---|
| Runtime और UI एक stack में | Model parameters समझने पड़ सकते हैं |
| CPU और GPU offload options | Hardware tuning beginner को complex लग सकती है |
| GGUF quantized models | Wrong quantization quality या speed प्रभावित करती है |
| Compatible API | Public network exposure को secure करना जरूरी है |
| Low overhead | Full team/admin features अलग platform जितने नहीं |
किसके लिए: Developers, command-line users और minimum overhead चाहने वाले। Same-machine use में server को localhost पर bind रखें। LAN या internet पर expose करने से पहले authentication, firewall और reverse proxy planning जरूरी है।
3. LobeChat: polished chat और specialised assistants
LobeChat modern interface, model switching और assistant-style workflows पर focus करता है। इसे self-host करके local model endpoint से जोड़ा जा सकता है। यह उन users के लिए अच्छा है जिन्हें basic terminal chat से अधिक polished experience और अलग-अलग tasks के लिए configured assistants चाहिए।
| Use case | Practical example |
|---|---|
| Role-based assistants | Writing, coding, research या support के लिए अलग instructions |
| Model switching | Small fast model और larger quality model के बीच selection |
| Self-hosted frontend | अपने domain या private network पर interface |
| Tool ecosystem | Specific workflows के लिए extensions or plugins |
किसके लिए: Users जिन्हें visual polish और configurable assistants चाहिए। Deployment से पहले current licensing, authentication, database और provider settings पढ़ें; frontend local होने का अर्थ model endpoint local होना जरूरी नहीं।
4. AnythingLLM: अपने documents से private answers
AnythingLLM document-heavy workflows के लिए useful है। अलग workspaces में PDFs, notes, manuals और internal files रखकर retrieval-based answers लिए जा सकते हैं। Desktop version personal use के लिए आसान है, जबकि server deployment team access के लिए बेहतर हो सकता है।
| Component | काम | Privacy check |
|---|---|---|
| Document loader | Files से text निकालता है | Supported formats और parser location देखें |
| Embedding model | Text को searchable vectors में बदलता है | Local embedding endpoint चुनें |
| Vector database | Relevant passages retrieve करता है | Storage path और backups protect करें |
| LLM | Retrieved context से answer बनाता है | Local model endpoint verify करें |
| Workspace permissions | Documents को projects में अलग रखता है | Multi-user access test करें |
किसके लिए: Research notes, product manuals, company policies और personal document assistant। याद रखें कि RAG answer source document से grounded हो सकता है, फिर भी hallucination समाप्त नहीं होती; critical facts original file में verify करें।
5. Jan: beginners के लिए desktop-first local AI
Jan Windows, macOS और Linux पर desktop application के रूप में local models चलाने का सरल रास्ता देता है। Model hub hardware fit दिखा सकता है और local models llama.cpp या supported Apple Silicon runtime से run हो सकते हैं। Compatible local API के कारण इसे अन्य tools से भी connect किया जा सकता है।
| Why beginners like it | What to check |
|---|---|
| Desktop installer | Operating-system compatibility |
| Built-in model discovery | Model size, quantization और license |
| Hardware fit indicator | Context size से memory use बढ़ सकती है |
| Offline local chat | Optional web or cloud features अलग data path बना सकते हैं |
| Local compatible API | Network binding and API access secure रखें |
किसके लिए: First-time local AI users और desktop workflow। Official Windows guidance के practical baseline के अनुसार 8GB RAM छोटे quantized models, 16GB लगभग 7B class और 32GB larger 13B class के लिए starting point हो सकते हैं; actual requirement model, quantization और context पर निर्भर करेगी।
6. LibreChat: team-ready multi-provider platform
LibreChat basic local chat से आगे agents, tools, search, authentication, multiple users और multiple providers वाला platform है। Docker setup में database और related services भी आते हैं, इसलिए personal desktop app की तुलना में deployment अधिक complex है लेकिन team control बेहतर मिलता है।
| Benefit | Operational responsibility |
|---|---|
| Multiple users | Registration policy, roles and password security |
| Many providers | API keys and per-provider privacy |
| Local endpoint support | Model server availability and network rules |
| Agents and tools | Tool permissions and prompt-injection defence |
| Conversation search | Database backup and retention policy |
किसके लिए: Technical teams जिन्हें one interface में local और approved cloud models चाहिए। Production deployment में default settings पर निर्भर न रहें; secrets, database, HTTPS, backups और update process define करें।
7. Chat UI: developers के लिए clean, controllable frontend
Chat UI एक developer-focused web frontend है जो OpenAI-compatible endpoint से models discover और use करता है। अगर आपके पास llama.cpp, Ollama-compatible bridge या दूसरा compatible inference server पहले से है, तो यह clean interface layer बन सकता है।
| Good fit | Not ideal when |
|---|---|
| Existing compatible model server | आप model runtime भी one-click चाहते हैं |
| Custom branding and deployment | आप technical configuration से बचना चाहते हैं |
| Developer-controlled authentication | आप desktop-only single-user app चाहते हैं |
| Frontend contribution/customisation | आप managed updates और support चाहते हैं |
किसके लिए: Developers और organisations जिनके पास inference backend मौजूद है और frontend पर control चाहिए। API base URL और model endpoint गलत configure होने पर requests intended local server की जगह remote service तक जा सकती हैं।
Hardware guide: RAM, VRAM और model size
Model parameter count अकेला memory requirement नहीं बताता। Quantization, context window, KV cache, batch size और GPU offload भी memory बदलते हैं। नीचे planning ranges हैं, guarantee नहीं।
| System memory | Practical starting class | Expected experience |
|---|---|---|
| 8GB RAM | 1B–3B quantized | Basic chat; limited context; other apps बंद रखने पड़ सकते हैं |
| 16GB RAM | 3B–7B quantized | Good beginner range; CPU speed varies |
| 32GB RAM | 7B–13B quantized | Better context and larger models |
| 64GB+ RAM | Larger quantized or multi-model workflows | More flexibility, but CPU inference still slow हो सकती है |
GPU planning
| VRAM | Typical use | Important caveat |
|---|---|---|
| No dedicated GPU | CPU inference with small GGUF | Works but response speed lower |
| 6GB | Small models or partial offload | Long context memory pressure बढ़ाता है |
| 8GB | Many 7B-class quantized workflows | Exact fit quantization-dependent |
| 12GB–16GB | Larger models, faster generation, vision options | Model and KV cache must still fit |
| 24GB+ | Large models or heavier context | Power, cooling and cost भी consider करें |
Apple Silicon में unified memory CPU और GPU के बीच shared होती है, इसलिए traditional VRAM table सीधे apply नहीं होती। Available memory में operating system और other applications का हिस्सा छोड़ें।
Quantization क्या है?
| Choice | Memory | Speed | Quality direction |
|---|---|---|---|
| Lower-bit quantization | कम | Hardware पर अक्सर बेहतर fit | Accuracy degradation अधिक हो सकती है |
| Balanced 4-bit class | Moderate | Consumer hardware के लिए popular | Good practical balance |
| Higher-bit quantization | अधिक | Memory bandwidth demand अधिक | Original model के करीब |
| Full/high precision | बहुत अधिक | Powerful hardware required | Maximum fidelity direction |
सबसे बड़ा model हमेशा best choice नहीं होता। छोटा task-specific model जो पूरी तरह GPU में fit हो, oversized model के slow CPU offload से बेहतर user experience दे सकता है।
Use case के अनुसार selection
| Need | Recommended starting option | Reason |
|---|---|---|
| Simple offline personal chat | Jan | Desktop-first easy setup |
| Minimum runtime overhead | llama.cpp WebUI | Direct model server and UI |
| Polished home server | Open WebUI | Models, files and users in one place |
| Private document assistant | AnythingLLM | Workspace and RAG focus |
| Custom assistants | LobeChat | Strong assistant-centric interface |
| Technical multi-user team | LibreChat | Authentication, agents and providers |
| Custom developer frontend | Chat UI | Compatible API-based architecture |
Privacy audit: “Local” कहने से पहले यह check करें
| Component | Question | Safe direction |
|---|---|---|
| Chat model | Endpoint localhost है या remote domain? | Approved local IP/localhost verify करें |
| Embeddings | Documents के chunks कहाँ भेजे जाते हैं? | Local embedding model चुनें |
| Web search | Queries किस provider को जाती हैं? | Sensitive prompts में disable करें |
| Speech | Audio local transcribe होता है? | Local speech model or explicit consent |
| Tools/MCP | Tool किन files और systems तक पहुंचता है? | Least privilege और allowlist |
| Telemetry | Usage or crash data भेजा जाता है? | Settings and privacy docs review करें |
| Backups | Chats और vector database encrypted हैं? | Encrypted storage and access control |
Security: local AI अपने आप safe नहीं है
- Model server को बिना authentication public internet पर expose न करें।
- Default ports को router पर forward करने से बचें।
- Docker images और dependencies regularly update करें।
- Downloaded model files trusted repositories और checksums से verify करें।
- Agents को full disk, shell और email access एक साथ न दें।
- Documents में मौजूद malicious instructions prompt injection कर सकती हैं।
- API keys source files या public repository में commit न करें।
- Team setup में per-user accounts, logs और revocation रखें।
Open-source software और open model license अलग हैं
| Asset | License controls | Before commercial use |
|---|---|---|
| Chat interface | Software modification and distribution | Current repository license पढ़ें |
| Runtime | Engine use and redistribution | Binary and library terms देखें |
| Model weights | Who may use model and for what | Model card and acceptable-use terms पढ़ें |
| Training data | Usually separately governed or not fully disclosed | High-risk output review करें |
| Generated output | Jurisdiction and provider/model terms | Legal and originality review रखें |
Open-source interface install करने से connected model automatically open-source नहीं हो जाता। इसी तरह publicly downloadable weights का commercial use unrestricted हो, यह भी जरूरी नहीं।
Local AI की वास्तविक लागत
| Cost area | Possible expense | How to control |
|---|---|---|
| Hardware | RAM, GPU, SSD upgrade | पहले छोटे model से benchmark करें |
| Electricity | Long inference sessions | Efficient quantization and sleep policy |
| Storage | Multiple models and document indexes | Unused models delete and backup policy |
| Maintenance | Updates, security and troubleshooting | Stable versions and documented setup |
| People time | Deployment and support | Use-case-specific simple stack |
| Quality gap | More human review | Right model and clear evaluation set |
30-minute decision checklist
- Use case लिखें: general chat, coding, documents, team या agents।
- System RAM, GPU VRAM और free SSD space note करें।
- पहले 3B–7B quantized model से speed test करें।
- Interface और runtime अलग हैं या bundled, confirm करें।
- Model, embedding और search endpoints inspect करें।
- एक non-sensitive sample workflow पूरा चलाएं।
- Quality, tokens per second, memory और failure rate record करें।
- Agent tools enable करने से पहले permissions restrict करें।
- Current software और model licenses save करें।
- तभी sensitive files या team users migrate करें।
Common mistakes
- Chat UI को model समझ लेना।
- सबसे बड़ा model download करना बिना memory check किए।
- Long context को free समझना; KV cache memory बढ़ाती है।
- Local frontend को cloud model से जोड़कर full privacy मान लेना।
- External embeddings और web search भूल जाना।
- Public port पर server बिना API key expose करना।
- Agents को unrestricted shell और files देना।
- Model output को factual guarantee मानना।
- License और commercial-use conditions ignore करना।
- Updates और backups का process न बनाना।
Final recommendation
अगर आप beginner हैं तो Jan से शुरुआत करना आसान है। एक complete browser workspace और home server चाहिए तो Open WebUI practical है। Documents primary use case हैं तो AnythingLLM देखें। Minimum overhead और direct GGUF control के लिए llama.cpp WebUI मजबूत है। Polished assistants के लिए LobeChat, technical teams के लिए LibreChat और custom frontend development के लिए Chat UI बेहतर fit हो सकता है।
Tool चुनने से ज्यादा महत्वपूर्ण है पूरा data path समझना। सही model size, local embeddings, restricted tools, secure network और human verification के साथ local AI privacy और control दे सकता है। गलत configuration में वही setup slow, insecure या unexpectedly cloud-dependent बन सकता है। Small pilot से शुरू करें, measurable tasks पर evaluate करें और केवल proven workflow को production में ले जाएं।
Article at a glance
| Written by | Devansh Kulkarni |
|---|---|
| Published | 28 Sep 2026, 07:30 AM IST |
| Reading time | 12 minutes |
| Topic | Ecommerce research and practical guidance |
Frequently Asked Questions
क्या local AI बिना internet के चल सकता है?
हाँ, यदि model, runtime, interface और required embeddings पहले से download हैं तथा web search या cloud API disable है। Initial downloads और updates के लिए internet लग सकता है।
Local AI चलाने के लिए minimum RAM कितनी चाहिए?
8GB RAM पर छोटे 1B–3B quantized models चल सकते हैं। 16GB practical beginner range है और 32GB larger models के लिए अधिक flexibility देता है। Exact need model, quantization और context पर निर्भर है।
क्या local AI पूरी तरह private होता है?
केवल तभी जब model endpoint, embeddings, documents, speech और tools सभी local हों। Cloud API, external search या remote embedding enable होने पर संबंधित data बाहर जा सकता है।
Beginners के लिए सबसे आसान विकल्प कौन-सा है?
Desktop-first setup के कारण Jan एक आसान starting option है। Browser-based complete workspace के लिए Open WebUI useful हो सकता है, लेकिन Docker और backend configuration समझनी होगी।
अपने documents से questions पूछने के लिए कौन-सा tool अच्छा है?
AnythingLLM document workspaces और RAG पर focus करता है। Open WebUI भी knowledge features देता है। Sensitive documents के लिए local embedding और local model दोनों verify करें।
क्या dedicated GPU जरूरी है?
नहीं। छोटे quantized GGUF models CPU पर चल सकते हैं, लेकिन response धीमा हो सकता है। Compatible GPU और sufficient VRAM generation speed बेहतर कर सकते हैं।
क्या open-source interface के साथ हर model commercial use के लिए free है?
नहीं। Interface, runtime और model weights की licenses अलग होती हैं। Commercial deployment से पहले हर component की current license और acceptable-use terms पढ़ें।
Local AI server को internet पर खोलना safe है?
Default configuration में नहीं मानना चाहिए। Authentication, HTTPS reverse proxy, firewall, limited CORS, updates और access logs के बिना public exposure न करें।
Devansh Kulkarni
Data and Digital Platforms WriterDevansh explains platform changes, digital measurement and technology trends through practical, evidence-led reporting.
View author profileRead More Blogs
भारत में YouTube Shopping का बड़ा विस्तार: Amazon, AJIO और Meesho जुड़ने से क्या बदलेगा?
YouTube Shopping Affiliate Programme भारत में Amazon, AJIO, Meesho, Snapdeal और Tata CLiQ जैसे नए retail partners के साथ बढ़ रहा है। आसान भाषा में समझिए कि creators, brands और खरीदारों के लिए इसका क्या अर्थ है।
16 · Read blog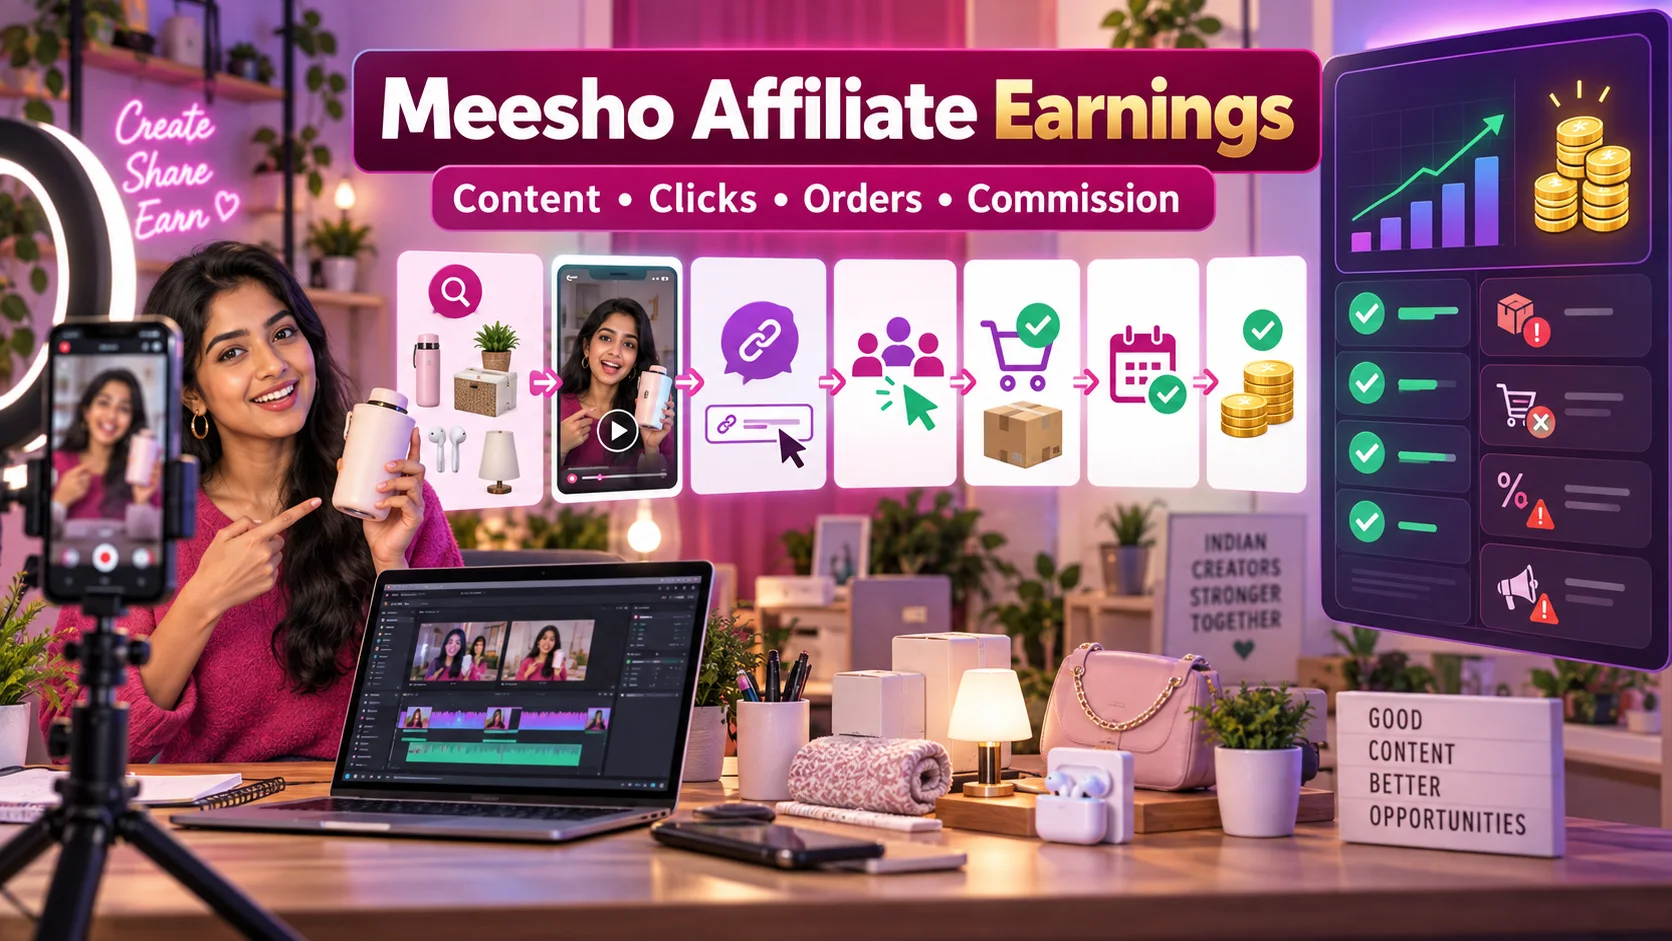
Meesho Affiliate Marketing से कमाई कैसे होती है? Influencers के लिए Complete Guide
Meesho products पर affiliate content बनाकर earnings कैसे calculate और track करें? Influencers के लिए content funnel, commission validation, returns, disclosure, payout और fraud safety की practical Hindi guide।
11 · Read blog
Meesho Affiliate Registration से Payout तक: Complete Step-by-Step Guide
Meesho affiliate registration, KYC, campaign selection, product-link creation, tracking test, rejected transactions और payout reconciliation का practical Hindi workflow।
4 · Read blog
Instagram Algorithm 2026 कैसे काम करता है? Feed, Reels, Stories और Explore की Complete Guide
Instagram Feed, Reels, Stories और Explore की ranking को समझने, reach diagnose करने और data-driven content strategy बनाने की detailed Hindi guide।
4 · Read blog
Comments 0
No comments yet. Be the first to share a useful thought.
Leave a comment
Your email address will not be published. Comments are reviewed before appearing. Web addresses are displayed as plain text and are never clickable.